[논문 리뷰] QPTQ
GPTQ는 Transformer 기반 대규모 언어 모델(LLM)에 대해 Post-Training Quantization (PTQ)을 적용하여, 매우 빠르고 효율적인 완전 정수 양자화를 가능하게 한 연구입니다.
GPTQ는 당시 IST Austria 소속의 Elias Frantar가 제1저자로 주도하였으며, 2023년 ICLR에 발표되었습니다.
Optimal Brain Quantizer (OBQ)
Goal
\[\arg\min_{\widehat{W}_\ell} \; \| W_\ell X_\ell - \widehat{W}_\ell X_\ell \|_2^2\]Quantization으로 인한 최종 출력 오차를 최소화 하는 것을 목표로 합니다.
Method
\[w_q = \arg\min_{w_q} \frac{\text{(quant}(w_q) - w_q)^2} {[\mathbf{H}_F^{-1}]_{qq}}\]현재 weight $w_q$를 quantization grid에 맞춰, normalized error를 최소화하는 방향으로 양자화(bin)을 선택합니다.
\[\delta_F = -\frac{w_q - \text{quant}(w_q)}{[\mathbf{H}_F^{-1}]_{qq}} \cdot (\mathbf{H}_F^{-1})_{:,q}\]양자화로 생긴 오차를, Hessian inverse 열벡터에 따라 남은 weight로 보정(delta-correction) 합니다.
\[\mathbf{H}^{-1}_{-q} = \left( \mathbf{H}^{-1} - \frac{1}{[\mathbf{H}^{-1}]_{qq}} \mathbf{H}^{-1}_{:,q} \mathbf{H}^{-1}_{q,:} \right)_{-p}\]양자화한 $w_q$를 제거하고, 남은 weight 서브셋에 대해 갱신된 Hessian inverse를 계산합니다.
GPTQ
Arbitrary Order Insight
GPTQ에서 weight quantization 순서를 자유롭게 선택해도 수학적으로 일관된 결과를 얻을 수 있다는 통찰입니다.
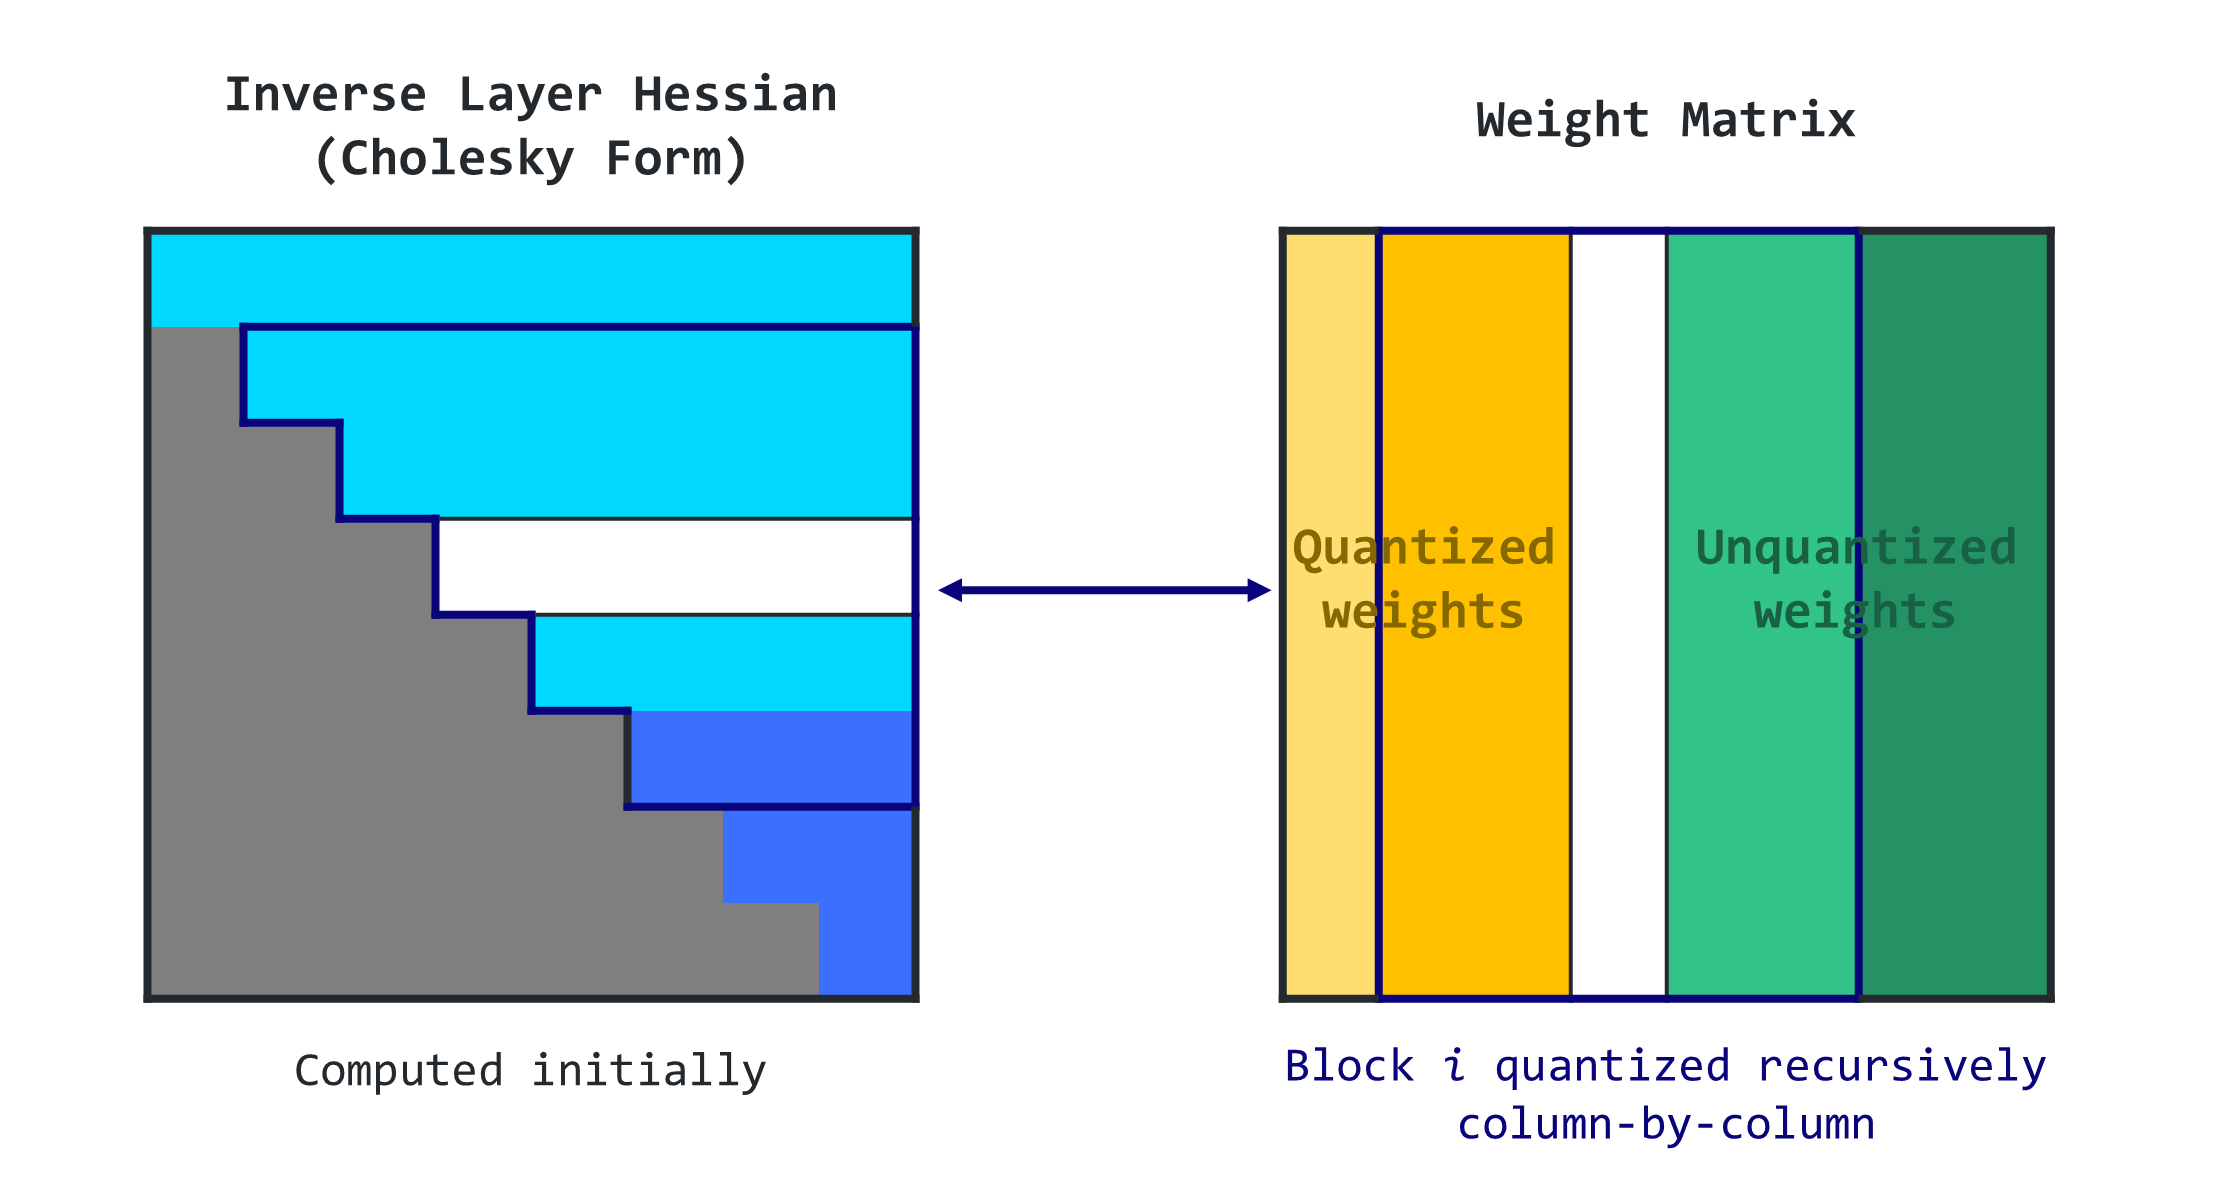
Lazy Batch-Updates
여러 weight 업데이트를 한 번에 모아서 처리합니다.
\[\delta_F = -\left( \mathbf{w}_Q - \text{quant}(\mathbf{w}_Q) \right) ( \left[ \mathbf{H}_F^{-1} \right]_{QQ} )^{-1} ( \mathbf{H}_F^{-1} )_{:,Q}\] \[\mathbf{H}_Q^{-1} = \left( \mathbf{H}^{-1} - \mathbf{H}_{:,Q}^{-1} \left( \left[ \mathbf{H}_F^{-1} \right]_{QQ} \right)^{-1} \mathbf{H}_{Q,:}^{-1} \right)_{-Q}\]Cholesky Reformulation
Hessian의 역행렬을 직접 계산하지 않고 Cholesky 분해를 이용합니다.
\[\mathbf{H}^{-1} = (LL^T)^{-1} = \text{Solve}(L, L^T, I)\]$\text{Solve}(L, L^T, v)$ 는 다음과 같이 전개된다.
\[\begin{align*} A &= LL^T \\ Ax &= v \\ LL^T x &= v \\ Ly &= v \quad &&\text{(Forward Substitution)} \\ y_i &= \frac{1}{L_{ii}} \left( v_i - \sum_{j=1}^{i-1} L_{ij} y_j \right) \quad &&\text{for } i = 1, \dotsc, n \\ L^T x &= y \quad &&\text{(Backward Substitution)} \\ x_i &= \frac{1}{L_{ii}} \left( y_i - \sum_{j=i+1}^{n} L_{ji} x_j \right) \quad &&\text{for } i = n, \dotsc, 1 \end{align*}\]The Full Algorithm
Algorithm 1 Quantize W given inverse Hessian $\mathbf{H}^{-1} = (2\mathbf{X}\mathbf{X}^T + \lambda\mathbf{I})^{-1}$ and block size $B$
\[\newcommand{\for}{\text{for}} \newcommand{\do}{\text{do}} \newcommand{\endfor}{\text{end for}} \newcommand{\row}{\text{row}} \newcommand{\col}{\text{col}} \newcommand{\Cholesky}{\text{Cholesky}} \newcommand{\Q}{\mathbf{Q}} \newcommand{\E}{\mathbf{E}} \newcommand{\H}{\mathbf{H}} \newcommand{\W}{\mathbf{W}} \begin{align*} &Q \leftarrow \mathbf{0}_{d_\row \times d_\col} && \text{quantized output }\\ &E \leftarrow \mathbf{0}_{d_\row \times B} && \text{block quantization error} \\ &\H^{-1} \leftarrow \Cholesky(\H^{-1})^T && \text{Hessian inverse information} \\ &\for \ i = 0, B, 2B, \dots, \do \\ & \quad \for j = i, \dots, i + B - 1 \ \do \\ & \quad \quad \Q_{:, j} \leftarrow \text{quant}{\W_{:, j}} && \text{quantize column} \\ & \quad \quad \E_{:, j-i} \leftarrow (\W_{:, j} - \Q_{:, j}) / [\H^{-1}]_{jj} && \text{quantuzation error} \\ & \quad \quad \W_{:, j:(i+B)} \leftarrow \W_{:, j:(i+B)} - \E_{:, j-i} \cdot \H^{-1}_{j,j:(i+B)} && \text{update weights in block} \\ & \quad \endfor \\ & \quad \W_{:, (i+B):} \leftarrow \W_{:, (i+B):} - \E \cdot \H^{-1}_{i:(i+B), (i+B):} && \text{update all remaining weights} \\ & \endfor \end{align*}\]